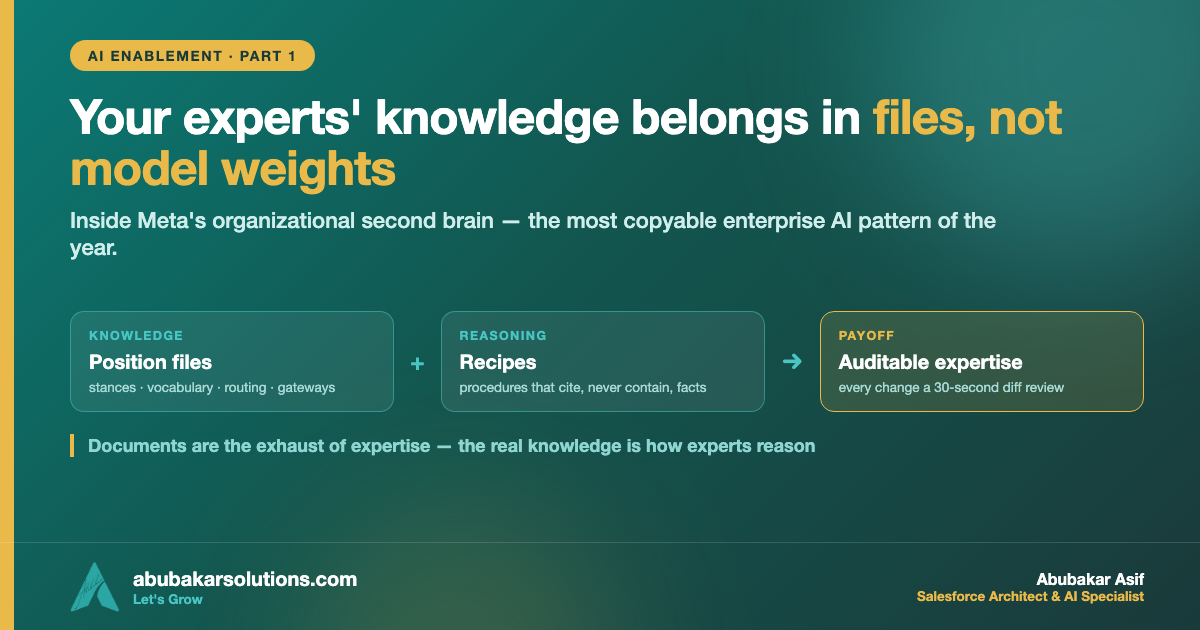
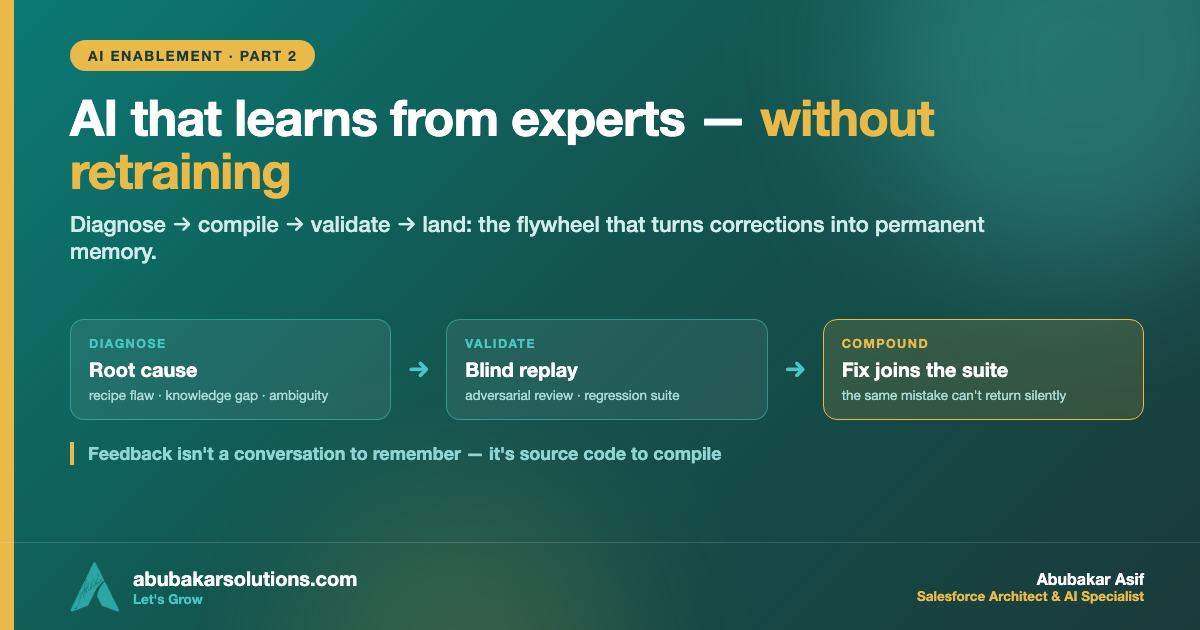
In part one I covered the architecture of Meta’s organizational second brain: expert knowledge as structured files, reasoning as composable recipes. This post is about the part Meta’s team calls the most distinctive — and the part I think every enterprise AI roadmap quietly lacks: the self-improvement flywheel. When a domain expert corrects the agent, that correction doesn’t evaporate into a chat log. It gets diagnosed to a root cause, compiled into a minimal file edit, validated against regression tests, reviewed by a human, and then folded into the test suite forever. No retraining. No fine-tune. Just text edits — proven, audited, and permanent. Here’s how the loop works, and why “learning without retraining” is the capability that separates AI systems that compound from AI systems that plateau.
What I’ll Cover in This Blog
✔️ Why expert feedback is the most wasted asset in enterprise AI
✔️ The four-phase loop: diagnose → compile → validate → land and enrich
✔️ The attribution test that replaces guessing with a binary question
✔️ The trust mechanics: adversarial review, blind replay, deterministic linting
✔️ What Meta reports it achieved — and the principle that transfers
Now, let’s dive in! 🔥
The Most Wasted Asset in Enterprise AI
Think about what happens today when your best expert corrects an AI assistant: the correction lands in a conversation, helps exactly one answer, and is gone. Next week the agent makes the same mistake for someone else. The expert’s time — the scarcest resource in the building — bought a single-use fix.
Meta’s team frames the underlying problem precisely. Their knowledge system has 200+ interdependent files, and translating expert feedback into correct file edits by hand means understanding the dependency graph, checking nothing else breaks, and proving the fix works — which can take weeks per correction. Lots of research exists on agent memory and model editing; much less on keeping a document-based institutional knowledge base correct as it grows. Their answer: treat maintenance as a compilation problem and automate it, with validation rigor at every step.
That framing is the unlock. Feedback isn’t a conversation to remember — it’s source code to compile.
Diagnosis: The Attribution Test
The first version of Meta’s diagnosis, by their own account, failed in an instructive way. They classified feedback by its conversational form: if the expert provided information, call it a knowledge gap; if they redirected the agent, call it a procedure problem. It didn’t work — how an expert phrases a correction is a poor proxy for what actually went wrong.
The working design separates extraction from classification. First, pull every substantive signal from the conversation, alongside the agent’s full knowledge manifest — every file it loaded, when, and how it used them. Then read those actual files and apply one test:
Could the agent have reached the correct conclusion from its source materials?
🔹 Materials contained the right answer, agent still erred → recipe problem. The methodology failed, not the knowledge.
🔹 Materials didn’t contain the right answer → knowledge gap. Add or amend a position file.
🔹 The experts themselves disagree → genuine ambiguity. No file edit; flag it for human discussion, because encoding one side of an unsettled debate is how knowledge bases rot.
Notice this test is only possible because of part one’s architecture: knowledge and reasoning live in separate layers, so the question has a binary answer. And notice the kinship with something smaller I’ve written about — the graduation loop in exception handling, where resolved exceptions carry reason codes so patterns become rules. Same philosophy, industrialized: corrections are labeled data about your own system, if you bother to label them.
Compilation and Its Trust Mechanics
The compiler turns a diagnosed issue into minimal edits — and “minimal” is doing real work in that sentence, because every unnecessary change is regression surface. Sub-agents analyze impact in parallel: cross-references, conflicts with existing positions, token budgets, duplication risk. But two mechanisms make the output trustworthy rather than merely plausible:
🔹 Independent adversarial review. A separate agent, in a fresh context, with no knowledge of why the change was proposed, receives only the diffs. Its one job: find what the change breaks — contradictions, broken edge cases, undermined positions. Because it shares no context with the proposer, it can’t inherit the proposer’s blind spots. This is the automated version of the reviewer who never attended your design meeting — annoying, and correct.
🔹 Deterministic structural validation. A linter catches dangling cross-references, identifier collisions, size-budget violations, dependency cycles. Not probabilistic. Pass or fail.
Then validation proper, in two stages. Targeted replay: rerun the original scenario that triggered the feedback — the agent doesn’t know it’s being tested, and a separate judge scores the new output against the expert’s feedback without knowing what changed. Deliberately blind, to kill confirmation bias. Regression testing: run the domain’s benchmark suites in parallel sessions; any regression sends the fix back to compilation with the failure report attached. The agent literally gets told where it regressed and tries again.
Landing and Enrichment: Why the Returns Compound
The pipeline’s output is a pull request with a full audit trail. The expert’s job inverts: instead of debugging a raw failure, they review a proven fix — diffs, replay results, regression results — in minutes. And the final step is the one that makes this a flywheel rather than a treadmill: the failing scenario and its validated correct answer join the regression suite automatically. Every future change must preserve the behavior that was just fixed.
Run that forward and you get the property every learning system wants: the bar only rises. Meta reports zero regressions across improvement cycles — not because the agents are infallible, but because the system is structured so that regressions get caught before landing, and every fix becomes a tripwire for the next one. It’s deploy-what-you-understand running at maintenance time: capability (automated edits) never outruns verification (a growing eval suite).
What Meta Reports — and What Transfers
After three sprints across six weeks, Meta’s post reports: expert assessments down from days to minutes, SMEs rating outputs useful almost all the time, validated knowledge edits produced at a rate that previously took full engineering sprints, and zero regressions — with every fix strengthening the suite. Their experts now spend their judgment on the genuinely ambiguous cases, which is the whole point.
You don’t need their infrastructure to steal the principles:
✔️ Treat corrections as data, not conversation. Capture them with enough context to diagnose (what the system knew when it erred).
✔️ Attribute before you fix. Knowledge gap, procedure flaw, or genuine ambiguity — three different fixes, and the third one is a meeting, not an edit.
✔️ Make every fix minimal, reviewed, and blind-tested. An adversarial reviewer with no context beats a proposer grading its own homework.
✔️ Grow the eval suite with every fix. The regression suite is your institutional memory of past failures — the cheapest moat in AI engineering.
✔️ Keep the human at the review gate. Automation proposes; experts dispose. Reviewing a proven diff takes thirty seconds; debugging a raw failure takes an afternoon.
Conclusion
✔️ Expert feedback is the most wasted asset in enterprise AI — single-use corrections on an infinite treadmill.
✔️ Meta’s flywheel compiles it instead: diagnose → compile → validate → land, with the fix folded into the regression suite forever.
✔️ The attribution test is the brain of the loop: could the agent have gotten it right from its materials? Recipe, knowledge, or ambiguity — in that order of questioning.
✔️ Trust is engineered, not assumed: adversarial review without shared context, blind replay, deterministic linting, retry-with-failure-report.
✔️ The returns compound because the bar only rises — zero regressions is a property of the structure, not of luck.
✔️ No retraining anywhere. Learning lives in reviewable text, which is exactly why it’s governable.
The organizations that win with AI won’t be the ones whose models are smartest on day one. They’ll be the ones whose systems are structured so that every correction makes tomorrow’s answer better — permanently. Part three shows how to build a scaled-down version of this with a mid-market team: Build a Second Brain for Your Business.
Does your AI assistant make the same mistake twice? Tell me the correction your experts are tired of repeating — that’s the first entry in your regression suite.
What’s the one correction your team has given an AI system more than five times? Tell me on LinkedIn.
About the Author — Abubakar Asif
SALESFORCE ARCHITECT · AI SPECIALIST · CLOUD ARCHITECT · PAKISTAN
Abubakar Asif — Salesforce Solution Architect, AI & Cloud Specialist based in Pakistan
Abubakar Asif is a Salesforce Solution Architect and artificial intelligence, Google Cloud and CRM specialist based in Pakistan — a top-rated AI, cloud infrastructure and Salesforce expert, and a National AI Research Engineer. He began as a core member and AI researcher with Google Developer Group, known for AI-powered brain-state recognition research, then built AI models and the applications around them for STEM education with STEM Wizards Academia, Toronto.
TRUE AI PIONEER · PRE-GENAI ERA
Abubakar is not just an AI adopter — he is a researcher who built models before “AI” became a buzzword. Before ChatGPT, Claude, Grok or Gemini existed, he was training and deploying custom neural networks from mathematical first principles.
A turn toward Salesforce and AI made him a Solution Architect, which opened the rest: CTO at Sunshine AI, where he led the technology and architecture that earned the startup Salesforce Consulting Partner status and drove healthy partner revenue; consultant and lead roles across Australia, Indonesia, the United States and the United Kingdom; and CTO at Shift Financial Planning, building next-generation financial planning powered by AI and Open Banking APIs.
Today he is Co-Founder and Chief Technology Officer at Kalala Consulting, leading AI, CRM and cloud architecture — Salesforce, Agentforce, Data 360, Google Cloud and Microsoft Azure — for clients across financial services, healthcare, education and other industries. He writes here at abubakarsolutions.com about Salesforce architecture, Agentforce and AI enablement, Google Cloud, and the data foundations that make all of it work.