The most valuable knowledge in any company has the same bad habit everywhere: it lives in people’s heads. The playbooks and wikis capture a fraction; the real thing — how your experts reason, what they prioritize, how they resolve ambiguity — walks out of the building every evening. In September, Meta’s engineering team published a detailed account of a system that attacks this directly: an AI agent that acts as a secondary expert, built on what they call an organizational second brain. I’ve read it closely, and I think it’s the most copyable enterprise AI pattern published this year. Here’s the architecture, and why its central principle — keep the complexity in text files, not model weights — should shape how you build.
What I’ll Cover in This Blog
✔️ The problem: expert knowledge is tribal, and retrieval alone doesn’t capture reasoning
✔️ The four-layer architecture Meta describes, and why each layer needs the others
✔️ The knowledge file taxonomy: positions, vocabulary, routing, gateways
✔️ Recipes: separating what the agent knows from how it reasons
✔️ Why “files, not fine-tunes” is the principle that makes all of it governable
Now, let’s dive in! 🔥
The Problem Retrieval Alone Can’t Solve
Every large organization accumulates thousands of documents as a byproduct of expert work, and it’s tempting to point an agent at them and call that institutional knowledge. Meta’s team names the flaw precisely: the documents are the exhaust of expertise, not the expertise. An agent that retrieves chunks at inference time has to re-derive the expert’s reasoning from raw sources on every single run — slow, error-prone, and inconsistent. A general-purpose model can tell you what an organization could do; it has no idea what that organization should do given its history, positions, and appetite for risk.
This matches what I see in enterprise AI work constantly: the gap between a demo that answers questions and a system that answers them the way your senior people would. Closing that gap is not a bigger-model problem or even purely a retrieval problem — it’s a knowledge-engineering problem. The mess has to be distilled before query time, which is the same discipline I’ve argued for since AI Won’t Fix Your Mess: organising is the job; the model is the configuration.
The Four Layers
Meta’s system stacks four layers, each solving a distinct problem — and the design insight is that they’re load-bearing together:
1️⃣ A structured knowledge system — the second brain itself: 200+ curated files stating how the organization interprets its domain, distilled offline from source documents by a long-running process.
2️⃣ A reasoning layer — explicit, composable procedures (“recipes”) that mirror how experts actually work through an analysis.
3️⃣ An evaluation framework — regression suites and judges that gate every change.
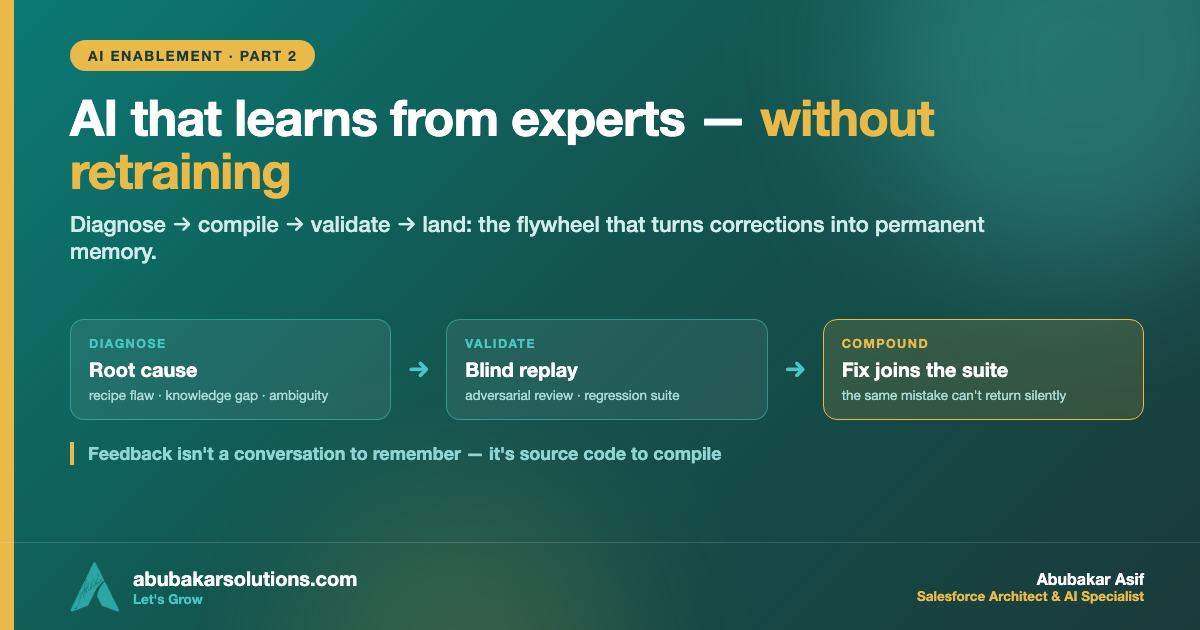
4️⃣ A self-improvement loop — expert corrections compiled into verified file edits, with no model retraining.
Remove any one and the others degrade: the file structure is what makes automated editing possible; the explicit procedures are what make failures attributable; the evals are what make automated edits trustworthy; the loop is what makes expert effort compound. (The loop deserves its own deep-dive — that’s part two.)
Inside the Second Brain: Four Kinds of Files
The knowledge system isn’t a document dump — it’s a strict taxonomy, and each file type answers a different failure mode:
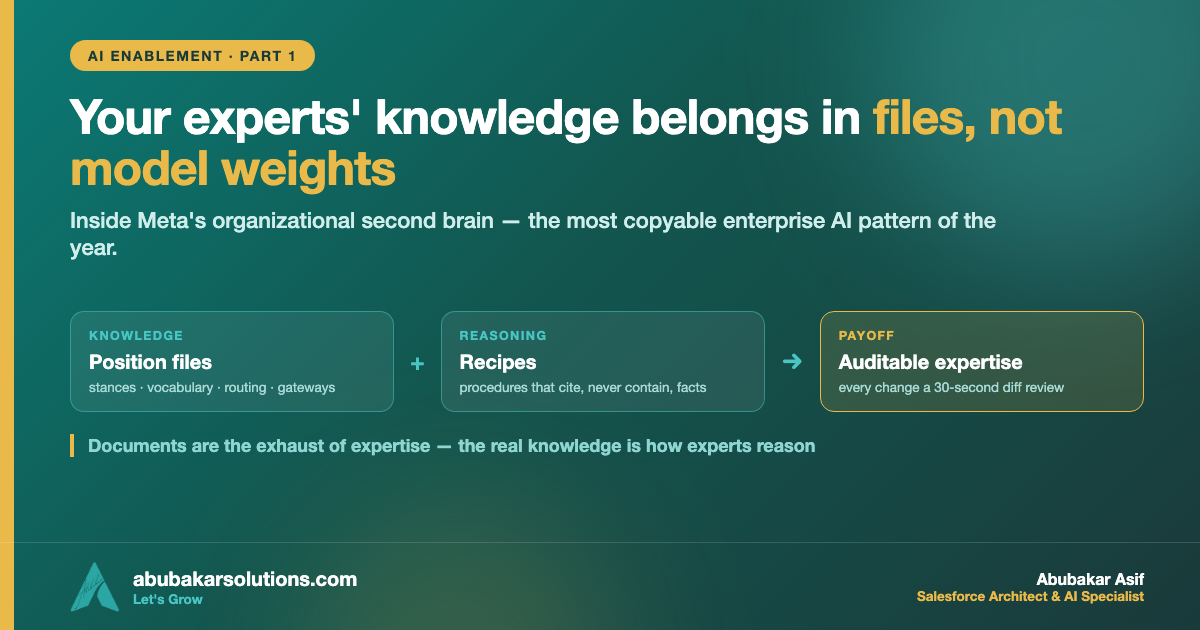
🔹 Position files capture authoritative organizational stances — how the company has decided to interpret a domain question, with constraints, boundary conditions, and machine-actionable routing hints. This is the “should,” not the “could.”
🔹 Taxonomy and vocabulary files are the single-source-of-truth glossary: entity types, categories, classification tiers. One definition per term, so the agent and the organization speak the same language.
🔹 Routing indexes map input characteristics to the relevant positions and procedures — deterministic, auditable retrieval instead of trusting embedding similarity to find the right rule.
🔹 Gateway files define threshold tests the agent must pass before entering a specialized domain at all — preventing confident expertise from being applied where it doesn’t belong.
Every file declares what it depends on and who consumes it in frontmatter, forming a bidirectional dependency graph. Change one file and you can trace exactly what else is affected — which is precisely what makes automated editing of the knowledge base safe later.
And note the split Meta makes with retrieval: high-density, frequently used knowledge lives in these curated files; sparse, situational material (specs, historical records) stays behind search. That’s the same economics I mapped in Cache the Stable, Retrieve the Volatile — the curated wiki is the stable canon, and RAG serves the long tail. The two patterns aren’t rivals; the second brain is what the “stable half” grows up into.
Recipes: What It Knows vs. How It Reasons
Knowledge alone doesn’t make an expert. Experts follow methodologies — a valuation model, a threat-modeling procedure, a compliance review sequence. Meta captures these as recipes: imperative, composable procedures that prescribe what to examine first, which knowledge files to load at each step, and what a complete analysis looks like. A top-level routing recipe picks sub-recipes the way a head chef’s master recipe delegates to the sauce and the protein without containing either.
The design rule is strict separation: recipes contain no domain facts; knowledge files prescribe no procedures. That buys three things:
🔹 Clean updates. A new organizational position = one knowledge file + a routing index entry. No recipe changes. A methodology fix = one recipe edit. No knowledge changes.
🔹 Clean failure attribution. When the agent errs, you can ask a binary question: was the knowledge wrong, or the procedure? (Part two shows how Meta automated exactly this question.)
🔹 Progressive disclosure. Each recipe step carries only the instructions and knowledge that phase needs. Meta reports that restructuring from one flat instruction file into recipe-driven stages cut tokens per turn by around 80% — and since attention degrades with volume, that’s a quality win, not just a cost one. It’s the context-engineering thesis from Prompt, Context, Agent made concrete: the right instructions at the right time beat all the instructions all the time.
Humans Stay in Charge — By Design
Two mechanisms keep experts in control: checkpoints, where the agent surfaces intermediate reasoning for review before proceeding, and escalations, where genuine ambiguity gets handed to the human instead of resolved by force. Meta notes these serve triple duty — quality control, training signal for the improvement loop, and trust calibration (experts watch the agent reason and flag uncertainty, rather than judging only final outputs). It’s the same human-in-the-loop geometry I’ve argued for in the exception-path playbook: the system detects its own limits, and the human’s decision becomes data.
Files, Not Fine-Tunes: Why This Is the Principle to Copy
Strip away the scale and one principle remains, stated plainly in Meta’s post: keep the complexity in text files readable by both humans and agents, not in fine-tuned model weights.
✔️ Every improvement is a text edit an expert can review in thirty seconds.
✔️ Every change is version-controlled, diffable, and reversible.
✔️ Knowledge survives model swaps — upgrade the LLM and the second brain comes along untouched.
✔️ Governance becomes git review, not ML ops.
✔️ And the organization can finally see its own expertise, instead of trusting that it’s somewhere in the weights.
Meta reports the results in its compliance domain: assessments that took days now take minutes, experts rate outputs useful almost all the time, and every fix permanently strengthens the regression suite. The pattern, they argue — and I agree — generalizes to any domain governed by retrievable text: finance, security review, engineering standards, procurement. How the self-improvement loop actually works is part two; what this looks like at mid-market scale, without a Meta-sized team, is part three.
Conclusion
✔️ Documents are the exhaust of expertise, not the expertise — the real knowledge is how experts reason, and it must be distilled before query time.
✔️ Four layers, all load-bearing: structured knowledge, recipe-based reasoning, gating evals, and a self-improvement loop.
✔️ The file taxonomy does the governing: positions, vocabulary, routing, gateways — with a dependency graph that makes change safe.
✔️ Separate knowing from reasoning — it makes updates surgical and failures attributable.
✔️ Progressive disclosure is a quality strategy: ~80% fewer tokens per turn, per Meta’s own report.
✔️ Files, not fine-tunes — reviewable in thirty seconds, diffable forever, portable across models.
Your organization already has a second brain. It’s just distributed across the heads of five senior people who can never be on vacation simultaneously. The pattern for writing it down finally exists.
Which five people in your company hold the knowledge that never got written down? Tell me the domain — that’s where a second brain starts.
Whose head is your organization’s single point of failure? Tell me on LinkedIn.
About the Author — Abubakar Asif
SALESFORCE ARCHITECT · AI SPECIALIST · CLOUD ARCHITECT · PAKISTAN
Abubakar Asif — Salesforce Solution Architect, AI & Cloud Specialist based in Pakistan
Abubakar Asif is a Salesforce Solution Architect and artificial intelligence, Google Cloud and CRM specialist based in Pakistan — a top-rated AI, cloud infrastructure and Salesforce expert, and a National AI Research Engineer. He began as a core member and AI researcher with Google Developer Group, known for AI-powered brain-state recognition research, then built AI models and the applications around them for STEM education with STEM Wizards Academia, Toronto.
TRUE AI PIONEER · PRE-GENAI ERA
Abubakar is not just an AI adopter — he is a researcher who built models before “AI” became a buzzword. Before ChatGPT, Claude, Grok or Gemini existed, he was training and deploying custom neural networks from mathematical first principles.
A turn toward Salesforce and AI made him a Solution Architect, which opened the rest: CTO at Sunshine AI, where he led the technology and architecture that earned the startup Salesforce Consulting Partner status and drove healthy partner revenue; consultant and lead roles across Australia, Indonesia, the United States and the United Kingdom; and CTO at Shift Financial Planning, building next-generation financial planning powered by AI and Open Banking APIs.
Today he is Co-Founder and Chief Technology Officer at Kalala Consulting, leading AI, CRM and cloud architecture — Salesforce, Agentforce, Data 360, Google Cloud and Microsoft Azure — for clients across financial services, healthcare, education and other industries. He writes here at abubakarsolutions.com about Salesforce architecture, Agentforce and AI enablement, Google Cloud, and the data foundations that make all of it work.