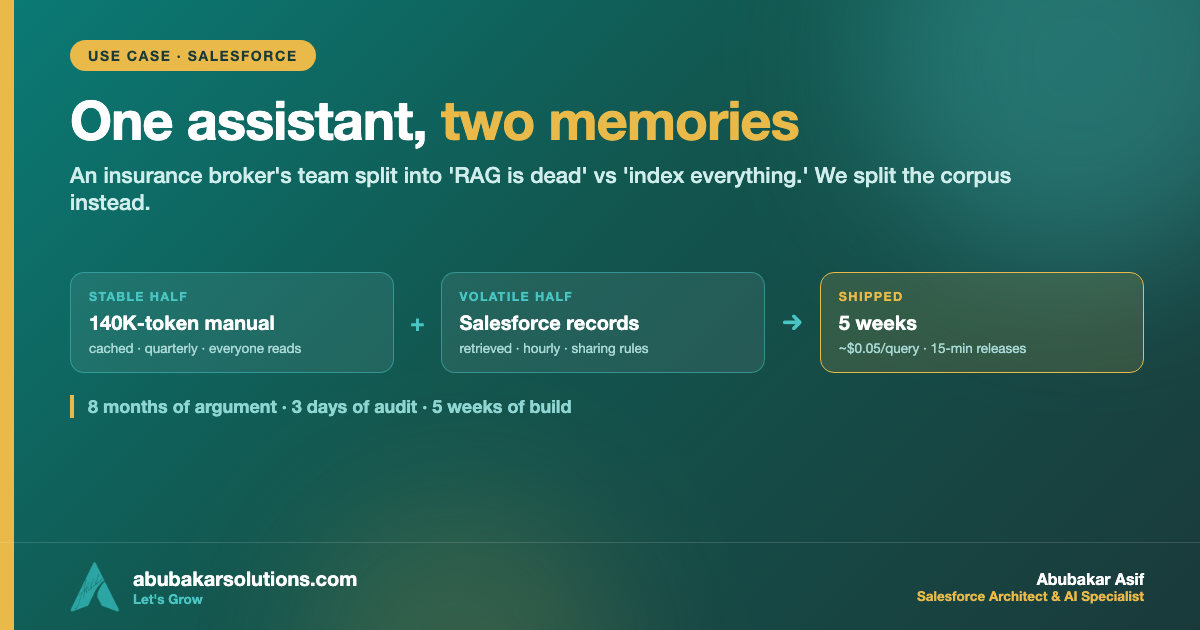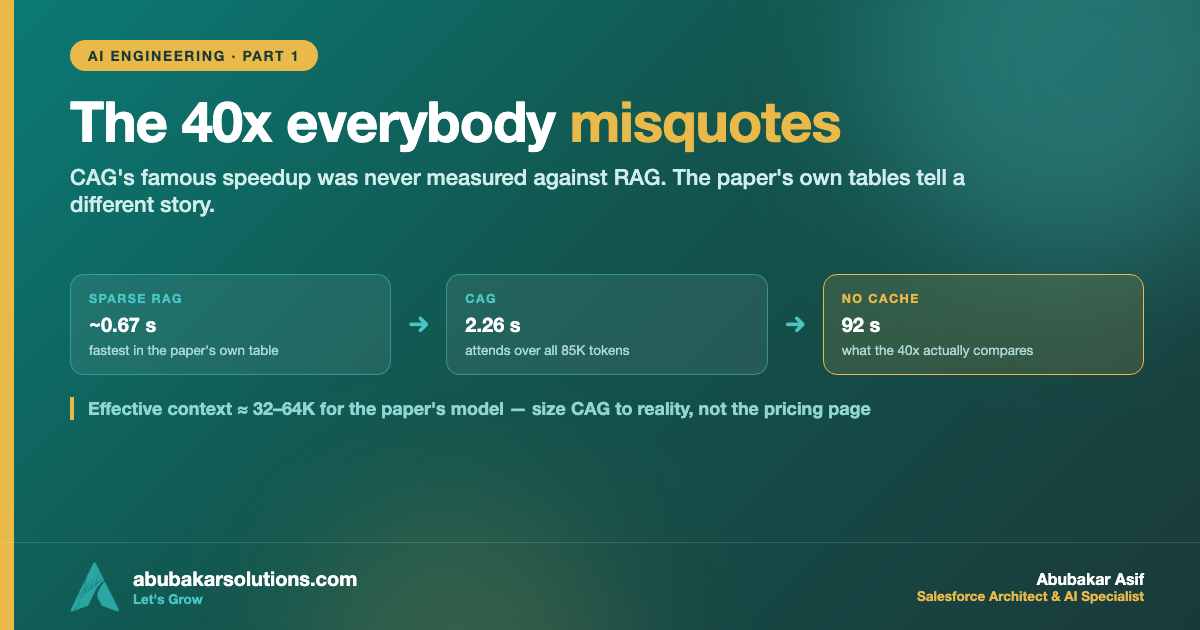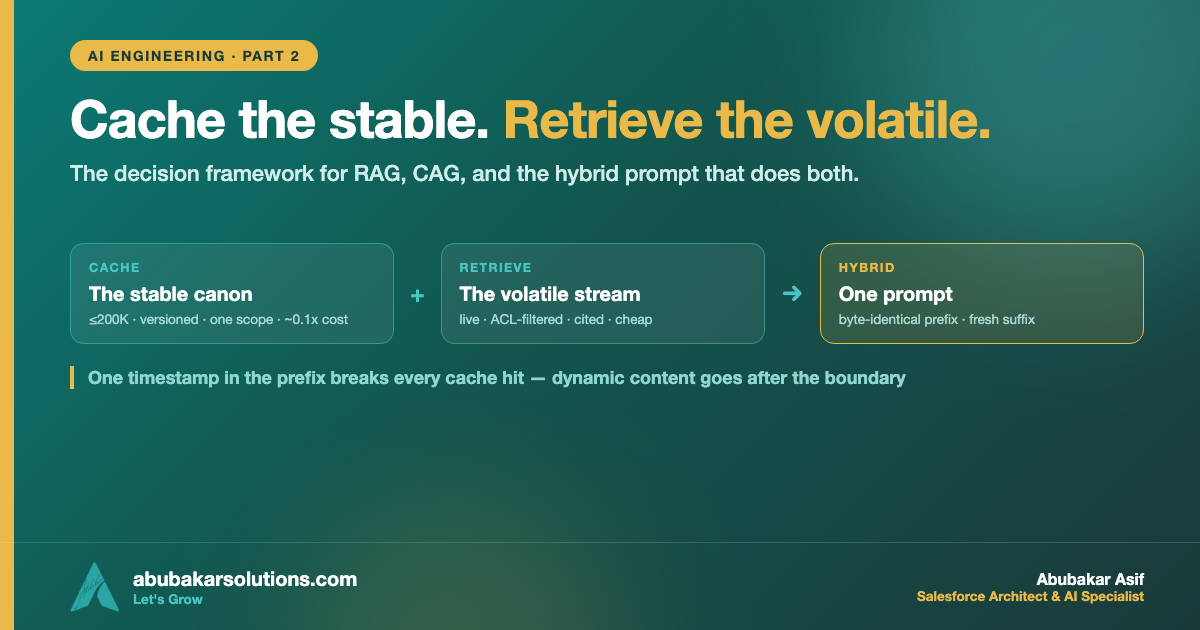
In part one I went through what the CAG paper actually measured and what the long-context research really says. This post is the practical half: the decision framework I use when a client asks “should we do RAG, or just put everything in the context window?” The answer is almost never a religion. It’s five questions about your corpus — and one sentence that resolves most architectures: cache the stable, retrieve the volatile.
What I’ll Cover in This Blog
✔️ The five conditions that must ALL hold before CAG is the right call
✔️ The conditions where retrieval is non-negotiable — scale, freshness, permissions, audit
✔️ The “RAG is dead” debate, read with the incentives visible
✔️ The hybrid prompt anatomy, and the byte-identical gotcha that silently breaks caching
✔️ A one-look decision map
Now, let’s dive in! 🔥
When CAG Wins: Five Conditions, All Required
CAG — the whole knowledge base living in a cached context — is genuinely the simplest architecture that works. But it earns that simplicity only when every one of these holds:
1️⃣ **The corpus fits the effective window with headroom.** Practical ceiling: ~100–200K tokens. That’s Anthropic’s own published guidance (~500 pages) in its Contextual Retrieval post, and it’s consistent with where the degradation research says accuracy stops being dependable.
2️⃣ Content is static or versioned. Policies, product manuals, a contract set, an underwriting guide. You rebuild the cache on release day — not continuously. Any change invalidates the prefix, so “edited hourly” and “cached prefix” are enemies.
3️⃣ One permission scope. Everyone who queries may see everything in the cache. The context window has no row-level security; if different users may see different documents, you’d need a cache per permission set — which stops being simple very fast.
4️⃣ Query volume keeps the cache warm. Provider caches are TTL-bound (minutes to an hour, depending on provider and tier). Steady traffic makes cached reads ~0.1x input cost; sparse traffic quietly pays the write premium over and over.
5️⃣ Questions need cross-document synthesis. This is CAG’s real superpower: no retrieval misses. When answers routinely need threads pulled from five documents at once, having everything in view beats hoping top-k catches all five.
When Retrieval Is Non-Negotiable
Any one of these puts you back in RAG territory — increasingly hybrid, reranked, and agentic:
🔹 Scale. The corpus exceeds the effective window or grows without bound. Enterprise knowledge is measured in terabytes, not tokens — no window fits it, and none is coming that will.
🔹 Freshness. Tickets, CRM records, inventory, news. Retrieval re-indexes the changed document; caching rewrites the world.
🔹 Permissions. Document ACLs, multi-tenancy, row-level security. Filter at retrieval time with metadata — never trust a prompt to enforce access. (This is the same permission-aware discipline that makes Salesforce-hosted MCP access safe: the enforcement lives in the data layer, not the model.)
🔹 Audit. Chunk-level citations for regulatory traceability come naturally from retrieval; attributing an answer to a specific passage inside a 200K-token cached blob does not.
🔹 Per-query cost at volume. Verified math from part one, on current Claude Sonnet 5 pricing: a 500K-token cached corpus costs ~$0.10 of input per warm query; a 5K-token retrieved prompt costs ~$0.01. A 10x gap, compounding with every query, forever.
The “RAG Is Dead” Debate, With Incentives Visible
Two of the sharpest quotes in this debate come from people with skin in the game — on opposite sides.
🔹 Boris Cherny, creator of Claude Code at Anthropic, on why they dropped their vector DB: agentic search “generally works better… It is also simpler and doesn’t have the same issues around security, privacy, staleness, and reliability.” Real, and important — with a caveat he gave himself: this was code, where grep-style exact match shines, and the eval was “mostly vibes” plus internal benchmarks.
🔹 Douwe Kiela, who co-created RAG at Meta and now runs a retrieval company: “Claiming that large LLM context windows replace RAG is like saying you don’t need hard drives because there’s enough RAM.” Also real, also important — from someone who sells the hard drives.
Read enough of these and the pattern is clear: most “RAG is dead” takes come from long-context enthusiasts; most rebuttals come from retrieval vendors. The neutral evidence — the academic long-context studies, the cost math, the CAG paper’s own tables — supports neither funeral nor status quo. It supports a workload decision. And notice what “agentic search” actually is: retrieval, run at answer time, by the model. The pipeline changed owners; the need didn’t move. It’s the same lesson as the orchestration-layers argument: the layer evolves, the job remains.
The Hybrid Default: Anatomy of the Prompt
Most real systems I design end up hybrid, and the prompt itself shows the split:
🔹 Cached prefix (stable, byte-identical): system instructions, tool schemas, and a curated “core knowledge pack” — the 50–150K tokens of policy, product truth, and terminology that every conversation needs. Written once per release, read at ~0.1x cost thousands of times.
🔹 Uncached suffix (volatile, per-query): retrieved chunks, fresh records, user context, and the question itself. Small, cheap, current, permission-filtered at fetch time.
🔹 A router where it pays: send lookup-style questions down the retrieval path and synthesis-heavy questions to the long-context path — the Self-Route pattern from the Google/Michigan study, which kept long-context quality at a fraction of the cost.
That warning strip is the most expensive lesson in this whole topic, so once more in prose: cache hits require a 100% identical prompt prefix. Put the dynamic content — dates, user names, retrieved text — after the cached block, always. Teams burn weeks confused about their bill because someone prepended “Today is Tuesday” to the system prompt.
The Cost Picture, Side by Side
On current verified pricing (Claude Sonnet 5, September 2026 — the same shape holds across the major providers, which now discount cached reads by roughly 90%):
Conclusion
✔️ CAG needs all five: fits the effective window, static content, one permission scope, warm-cache traffic, synthesis-heavy questions.
✔️ Any one of these forces retrieval: unbounded scale, hourly freshness, ACLs and multi-tenancy, chunk-level audit, per-query cost at volume.
✔️ The debate is mostly incentives: long-context enthusiasts vs retrieval vendors — while agentic search quietly proves retrieval by being retrieval.
✔️ The hybrid default wins: stable pack in a byte-identical cached prefix, volatile content retrieved into the suffix, a router for the edge.
✔️ Respect the byte-identical rule — one timestamp in the prefix and you’re paying full price while believing you’re cached.
✔️ Cache the stable. Retrieve the volatile. Write it on the whiteboard before the architecture meeting.
And if you want to see the framework survive contact with a real company — corpus fights, permission fights, and the bill that settled it — that’s part three.
Architecting a grounding layer right now and stuck between camps? Send me your corpus size, churn rate, and permission model — I’ll tell you which quadrant you’re in.
Which side of your knowledge base is bigger — the stable half or the volatile half? Tell me on LinkedIn.
About the Author — Abubakar Asif
SALESFORCE ARCHITECT · AI SPECIALIST · CLOUD ARCHITECT · PAKISTAN
Abubakar Asif — Salesforce Solution Architect, AI & Cloud Specialist based in Pakistan
Abubakar Asif is a Salesforce Solution Architect and artificial intelligence, Google Cloud and CRM specialist based in Pakistan — a top-rated AI, cloud infrastructure and Salesforce expert, and a National AI Research Engineer. He began as a core member and AI researcher with Google Developer Group, known for AI-powered brain-state recognition research, then built AI models and the applications around them for STEM education with STEM Wizards Academia, Toronto.
TRUE AI PIONEER · PRE-GENAI ERA
Abubakar is not just an AI adopter — he is a researcher who built models before “AI” became a buzzword. Before ChatGPT, Claude, Grok or Gemini existed, he was training and deploying custom neural networks from mathematical first principles.
A turn toward Salesforce and AI made him a Solution Architect, which opened the rest: CTO at Sunshine AI, where he led the technology and architecture that earned the startup Salesforce Consulting Partner status and drove healthy partner revenue; consultant and lead roles across Australia, Indonesia, the United States and the United Kingdom; and CTO at Shift Financial Planning, building next-generation financial planning powered by AI and Open Banking APIs.
Today he is Chief Technology Officer at Kalala Consulting, leading AI, CRM and cloud architecture — Salesforce, Agentforce, Data 360, Google Cloud and Microsoft Azure — for clients across financial services, healthcare, education and other industries. He writes here at abubakarsolutions.com about Salesforce architecture, Agentforce and AI enablement, Google Cloud, and the data foundations that make all of it work.